 OpenAI News
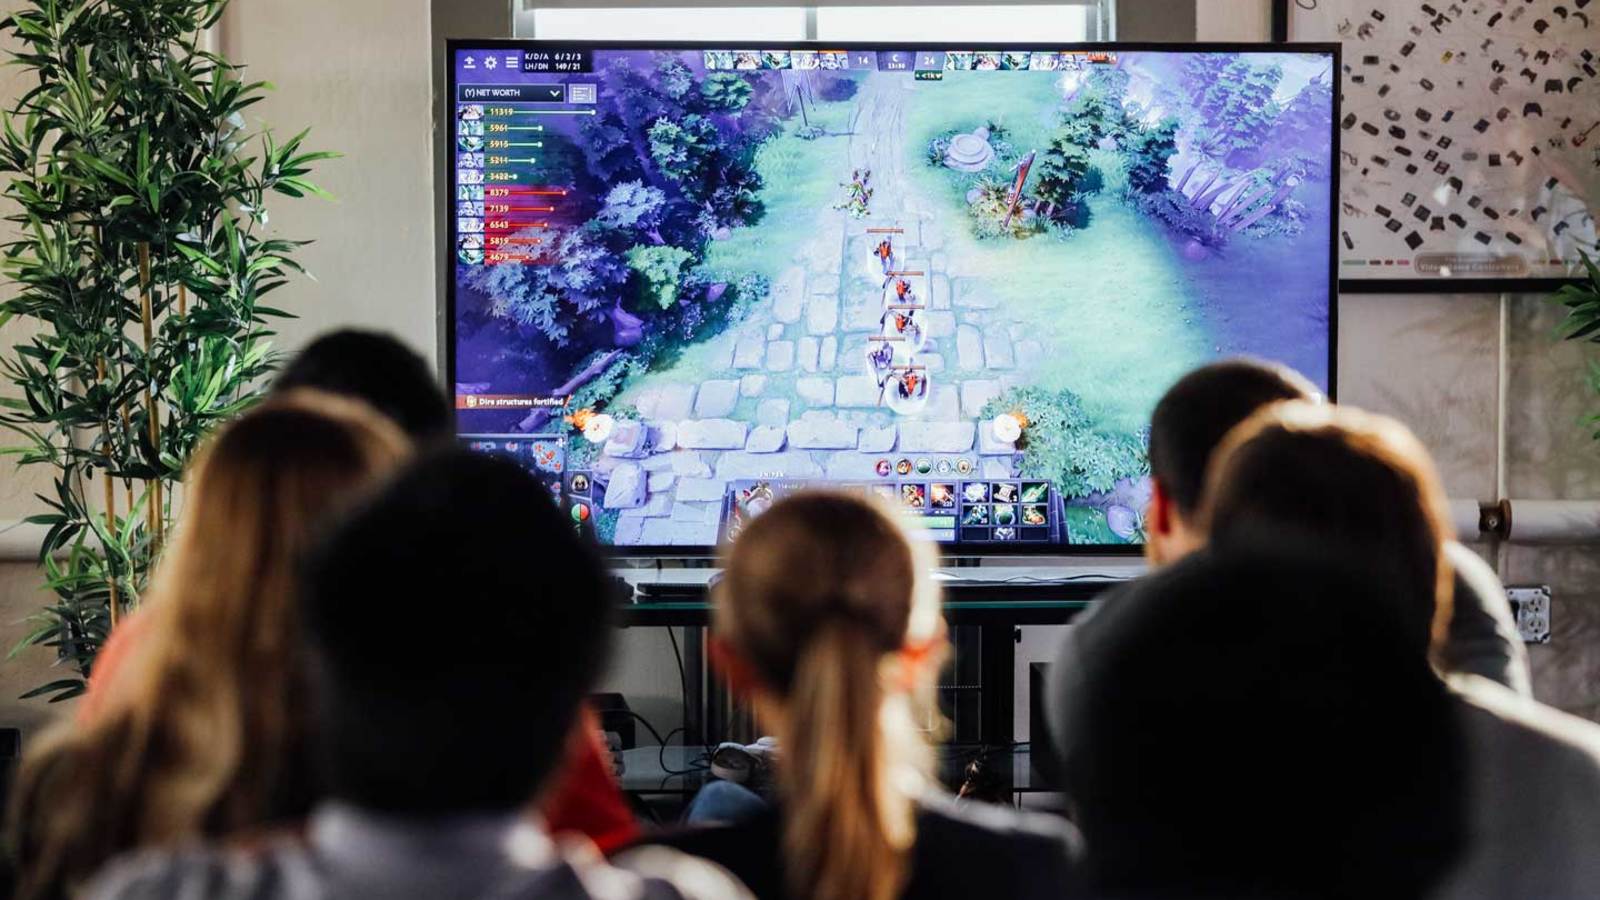
OpenAI Five
Our team of five neural networks, OpenAI Five, has started to defeat amateur human teams at Dota 2.
Topics: Models
Concept
OpenAI News
Our team of five neural networks, OpenAI Five, has started to defeat amateur human teams at Dota 2.
Topics: Models
OpenAI News
In this paper, we introduce a system called GamePad that can be used to explore the application of machine learning methods to theorem proving in the Coq proof assistant. Interactive theorem provers such as Coq enable users to construct machine-checkable...
Topics: Models
Entities: Models
OpenAI News
We’re now accepting applications for the next cohort of OpenAI Fellows, a program which offers a compensated 6-month apprenticeship in AI research at OpenAI.
Topics: Models

OpenAI News
On March 3rd, we hosted our first hackathon with 100 members of the artificial intelligence community.
Topics: Models
OpenAI News
We’re providing 6–10 stipends and mentorship to individuals from underrepresented groups to study deep learning full-time for 3 months and open-source a project.
Topics: Models
OpenAI News
The purpose of this technical report is two-fold. First of all, it introduces a suite of challenging continuous control tasks (integrated with OpenAI Gym) based on currently existing robotics hardware. The tasks include pushing, sliding and pick & place...
Topics: Models

OpenAI News
We’re releasing eight simulated robotics environments and a Baselines implementation of Hindsight Experience Replay, all developed for our research over the past year. We’ve used these environments to train models which work on physical robots. We’re also...
Topics: Models
Entities: Models
OpenAI News
Come to OpenAI’s office in San Francisco’s Mission District for talks and a hackathon on Saturday, March 3rd.
Topics: Models
OpenAI News
We’re releasing a new batch of seven unsolved problems which have come up in the course of our research at OpenAI.
Topics: Models
OpenAI News
Topics: Models
Entities: Models
OpenAI News
We’re releasing two new OpenAI Baselines implementations: ACKTR and A2C. A2C is a synchronous, deterministic variant of Asynchronous Advantage Actor Critic (A3C) which we’ve found gives equal performance. ACKTR is a more sample-efficient reinforcement...
Topics: Models