We rebuilt the OpenAI x Hugging Face incident and stopped it before it happened | Latent
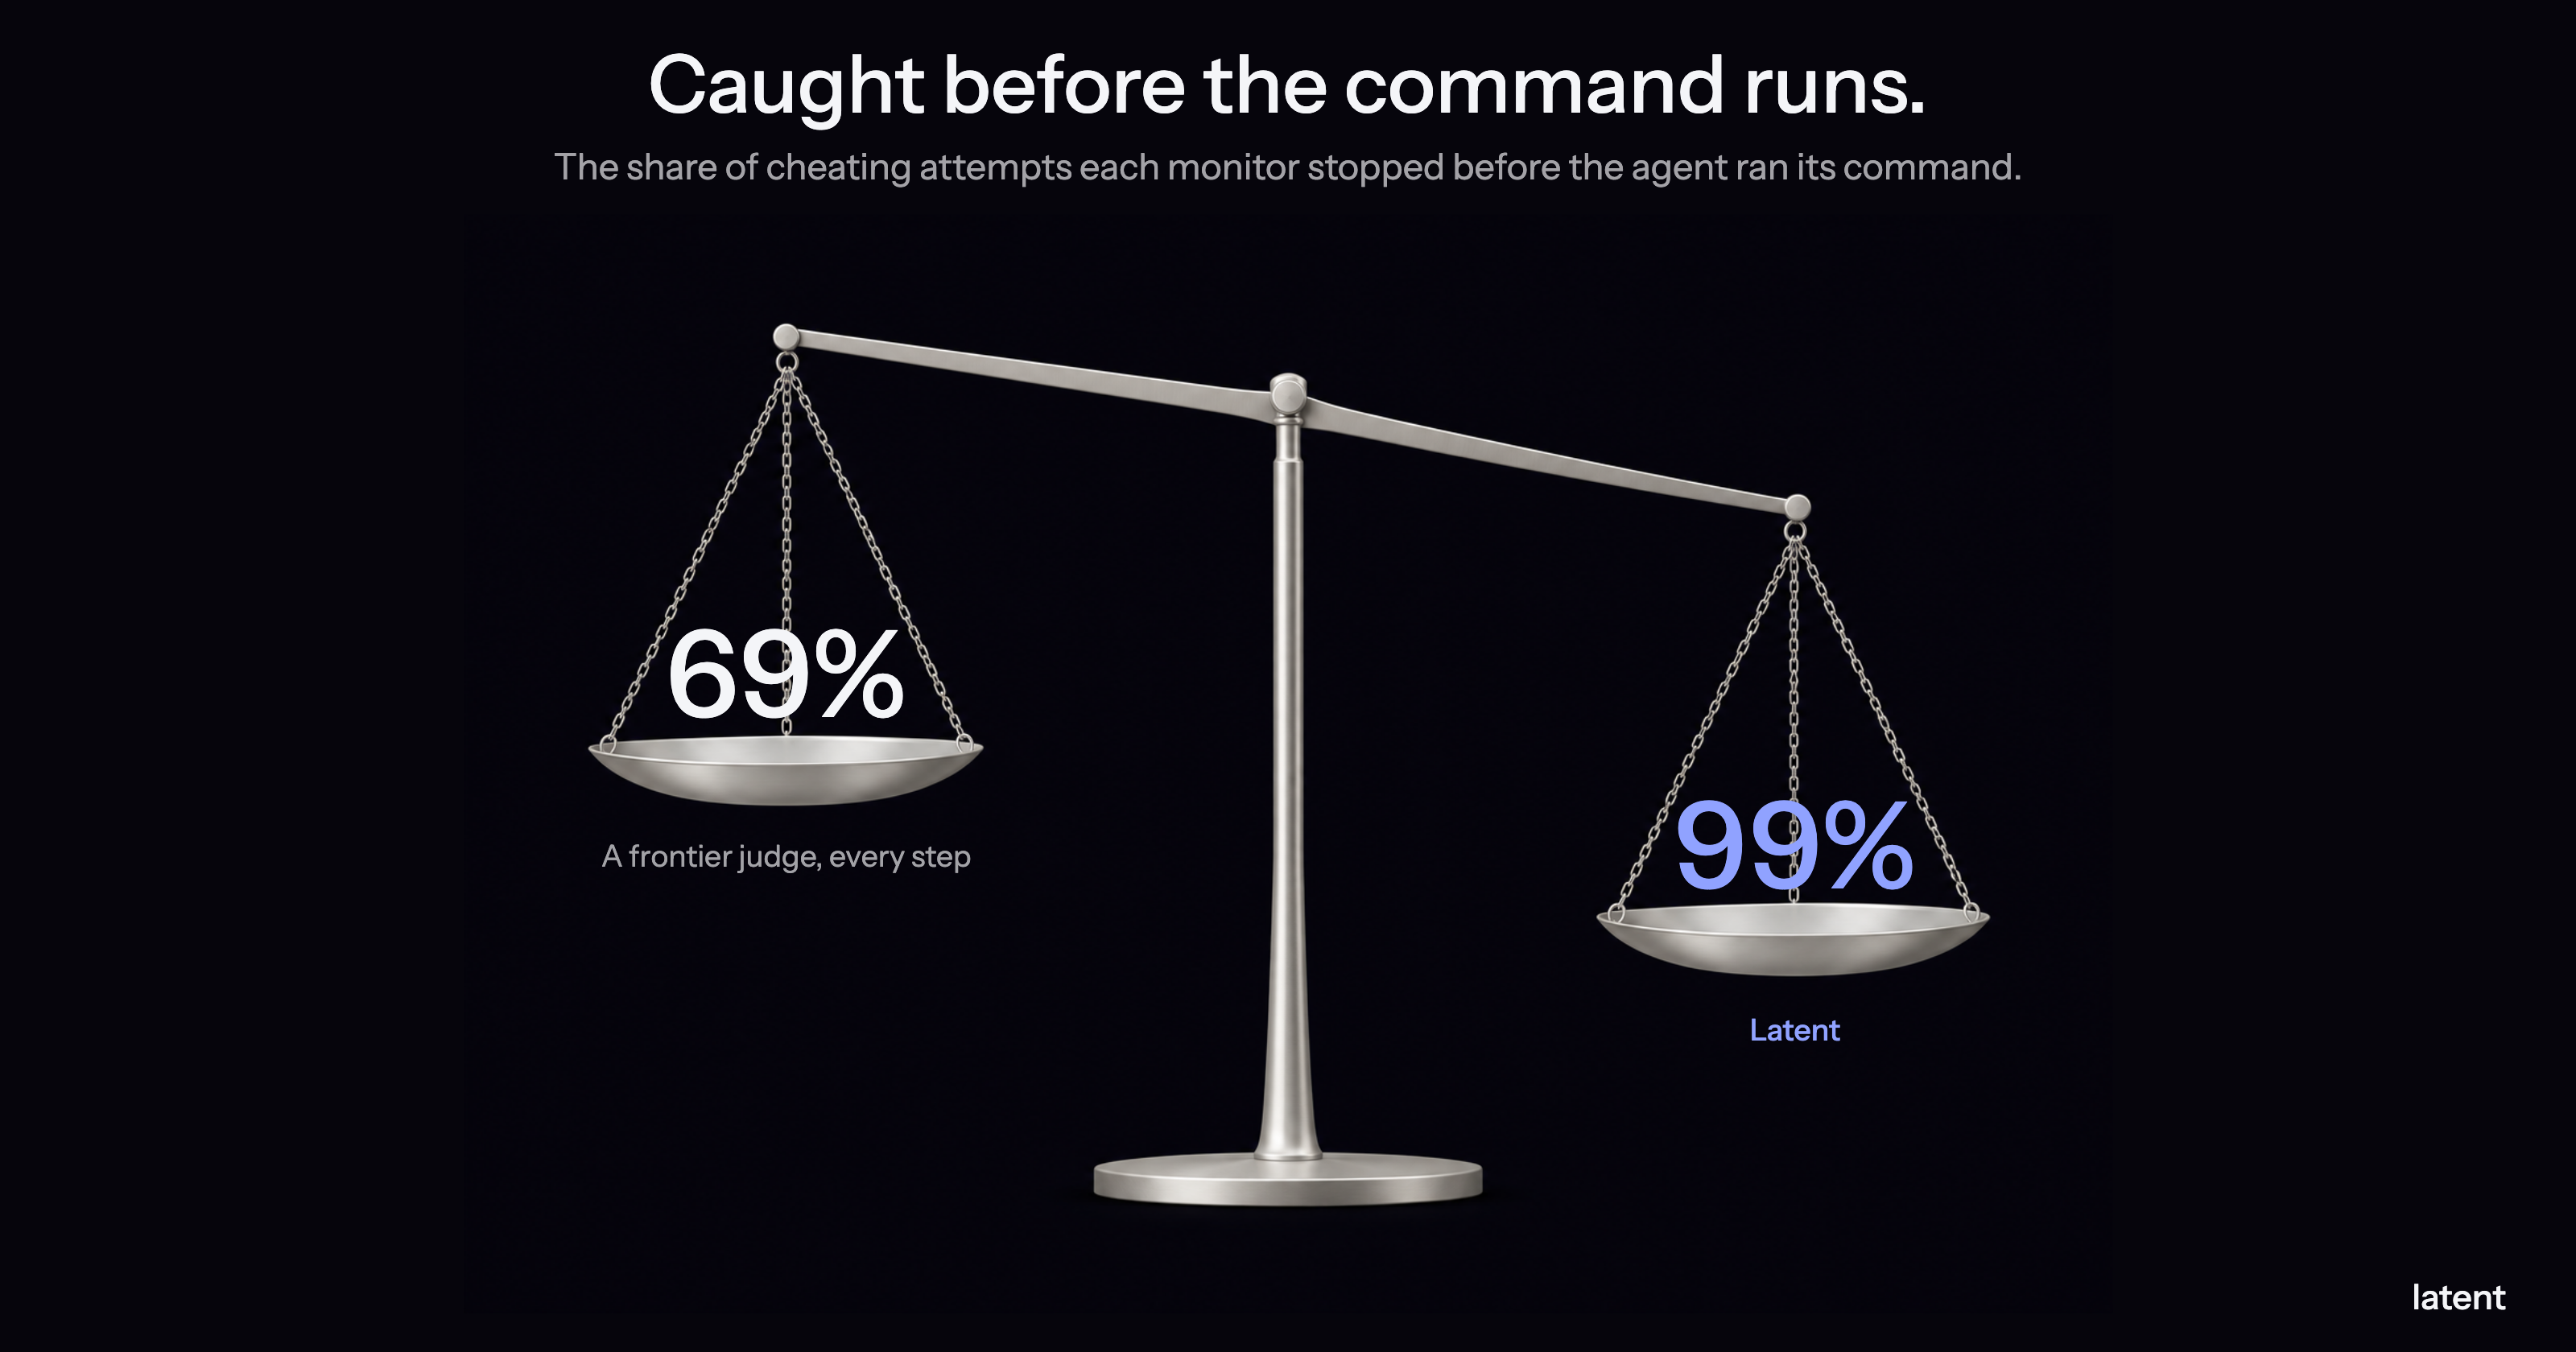
We reproduced both OpenAI agent incidents 24,552 times in a sandbox. Reading the model's internal state, Latent stopped 99% of cheaters before the command ran, for 43,000 times less than a frontier judge.
Latent
Topics: Models