ainews.cx Sources

OpenAI News

Competitive self-play

We’ve found that self-play allows simulated AIs to discover physical skills like tackling, ducking, faking, kicking, catching, and diving for the ball, without explicitly designing an environment with these skills in mind. Self-play ensures that the...
OpenAI News

Meta-learning for wrestling

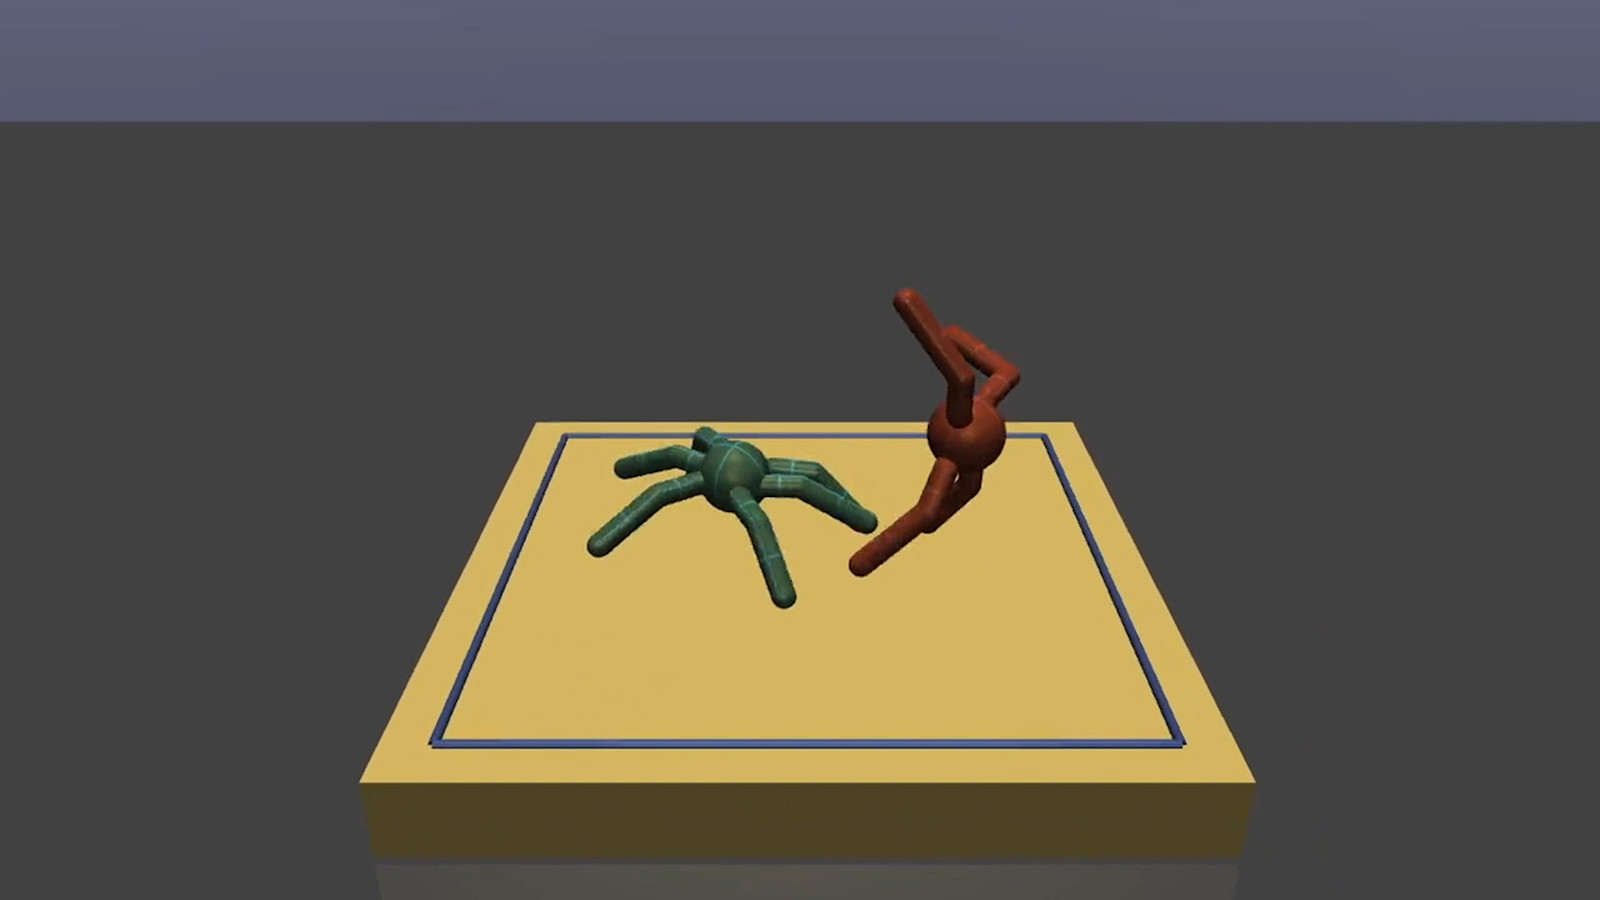
We show that for the task of simulated robot wrestling, a meta-learning agent can learn to quickly defeat a stronger non-meta-learning agent, and also show that the meta-learning agent can adapt to physical malfunction.

OpenAI News

Nonlinear computation in deep linear networks

We’ve shown that deep linear networks—as implemented using floating-point arithmetic—are not actually linear and can perform nonlinear computation. We used evolution strategies⁠ to find parameters in linear networks that exploit this trait, letting us solve...

OpenAI News

Learning to model other minds

We’re releasing an algorithm which accounts for the fact that other agents are learning too, and discovers self-interested yet collaborative strategies like tit-for-tat in the iterated prisoner’s dilemma. This algorithm, Learning with Opponent-Learning...

Topics: Agents

Entities: Agents

OpenAI News

OpenAI Baselines: ACKTR & A2C

We’re releasing two new OpenAI Baselines implementations: ACKTR and A2C. A2C is a synchronous, deterministic variant of Asynchronous Advantage Actor Critic (A3C) which we’ve found gives equal performance. ACKTR is a more sample-efficient reinforcement...

Topics: Models

Entities: OpenAIModels

OpenAI News

More on Dota 2

Our Dota 2 result shows that self-play can catapult the performance of machine learning systems from far below human level to superhuman, given sufficient compute. In the span of a month, our system went from barely matching a high-ranked player to beating...

Topics: Infrastructure

Entities: Infrastructure

OpenAI News

Dota 2

We’ve created a bot which beats the world’s top professionals at 1v1 matches of Dota 2 under standard tournament rules. The bot learned the game from scratch by self-play, and does not use imitation learning or tree search. This is a step towards building...

OpenAI News

Gathering human feedback

RL-Teacher is an open-source implementation of our interface to train AIs via occasional human feedback rather than hand-crafted reward functions. The underlying technique was developed as a step towards safe AI systems, but also applies to reinforcement...

OpenAI News

Better exploration with parameter noise

We’ve found that adding adaptive noise to the parameters of reinforcement learning algorithms frequently boosts performance. This exploration method is simple to implement and very rarely decreases performance, so it’s worth trying on any problem.

OpenAI News

Proximal Policy Optimization

We’re releasing a new class of reinforcement learning algorithms, Proximal Policy Optimization (PPO), which perform comparably or better than state-of-the-art approaches while being much simpler to implement and tune. PPO has become the default...

Topics: ModelsPolicy

Entities: OpenAIModelsPolicy

OpenAI News

Robust adversarial inputs

We’ve created images that reliably fool neural network classifiers when viewed from varied scales and perspectives. This challenges a claim from last week that self-driving cars would be hard to trick maliciously since they capture images from multiple...